A dashboard can look polished and still be wrong. If revenue, active customers, and conversion rates use different definitions across reports, meetings become debates about the business metrics guiding SaaS decisions.
A dbt metrics layer gives SaaS teams a single source of truth for shared metric definitions. The current dbt semantic layer depends on tested dbt data models. Analytics engineers review and maintain definitions before BI tools consume them, but it won’t fix weak source data alone.
Start with a small set of high-stakes SaaS metrics, then expand after reviewable definitions and testing establish data trust.
Key Takeaways
- Put shared metric definitions in trusted dbt models, not scattered dashboard calculations.
- Choose the grain of every semantic model before defining metrics or joins.
- Use entities for relationships, dimensions for slicing, and metrics for aggregation logic.
- Current dbt terminology centers on the dbt semantic layer and MetricFlow, not the deprecated
dbt_metricspackage. - Reconcile revenue and customer metrics against known periods, then check them for data quality.
- Watch warehouse query patterns closely, because flexible query-time computation can become expensive.
What a dbt Metrics Layer Does for SaaS Reporting
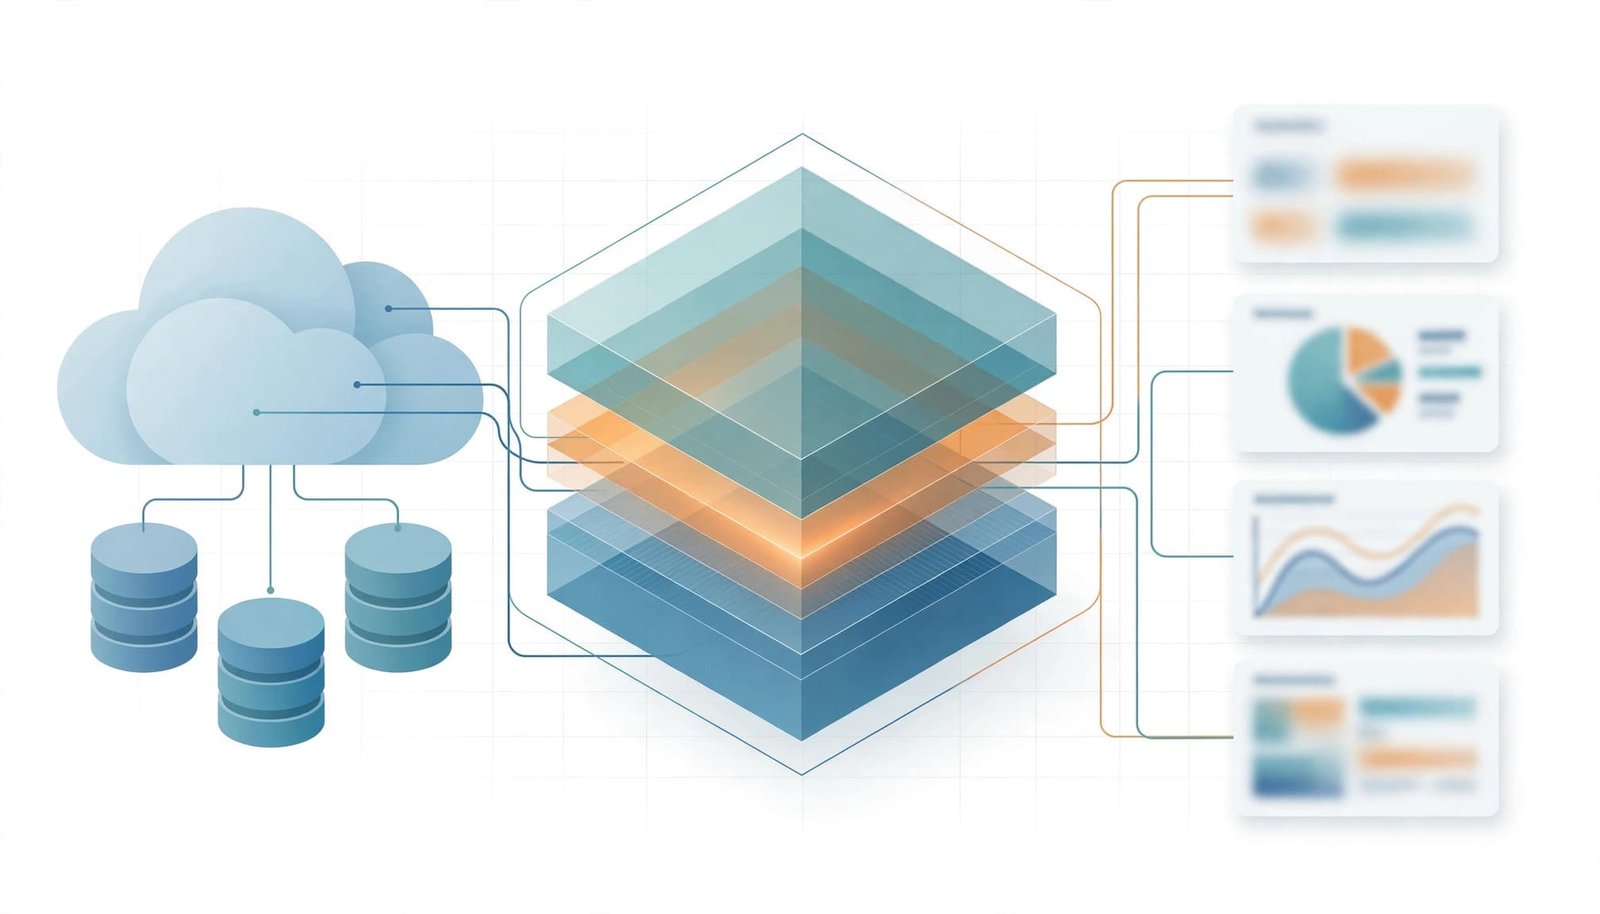
The dbt semantic layer sits between modeled warehouse data and the tools people use to explore it. Instead of rebuilding “monthly recurring revenue” in Looker, Metabase, spreadsheets, and board slides, the team agrees on one definition in the analytics project.
Centralize definitions before dashboards multiply
For a SaaS company, shared definitions usually start with business metrics that shape decisions:
- MRR, ARR, expansion revenue, and churned revenue
- Trial-to-paid conversion rate
- Active accounts or active users
- Sales pipeline created and pipeline conversion
- Customer acquisition cost and payback period
The goal isn’t to force every chart through one system on day one. It is to keep definitions tied to revenue, retention, and growth out of individual dashboard workbooks.
MetricFlow is the dbt component that interprets metric specifications and builds the SQL needed to answer a request. Your data warehouse remains the source of data and compute.
Keep the semantic layer out of the presentation role
Looker can centralize logic in LookML, while Tableau calculations often spread across workbooks. Metabase teams may rely on curated models and saved questions. These BI tools can support exploration, but their dashboard measures shouldn’t become the authoritative revenue definition.
Analytics engineers should keep core logic in curated dbt data models. Moving that logic out of dashboards makes a future BI change less painful.
A single source of truth only works when the source model has a clear grain, an owner, and tests that block bad data from reaching production.
Legacy dbt Metrics and the Modern Semantic Layer
The terms around dbt metrics have changed, so older tutorials can send teams in the wrong direction.
What changed after the original package
dbt deprecated the legacy dbt_metrics package and its earlier semantic layer on December 15, 2023. That older approach was supported only through dbt version 1.5 or lower.
The documented path moved metric specifications to the current architecture. If you inherit an older project, don’t copy its YAML or measures blindly into a new implementation. Review your installed release and consult dbt Labs documentation for its syntax as part of your data governance process.
How the current architecture differs
The modern dbt semantic layer uses semantic models as the foundation for shared definitions. MetricFlow then resolves valid joins, dimensions, and metric calculations at query time.
That differs from treating a metric as a standalone package object, with measures and disconnected assumptions about its data model. The newer approach starts with governed data models, their keys, and their time fields. It makes the relationship between a metric and its underlying data more explicit.
Design Semantic Models Around Grain and Relationships
Establish grain in the underlying data models before designing the dbt semantic layer or writing metric definitions. A semantic layer can’t safely repair a fact table that mixes subscription-level, account-level, and invoice-line-level records.
Pick one grain for each model
Each semantic model should expose a well-defined grain. A model’s grain states what one row represents. For example:
| Model | One row represents | Good uses |
|---|---|---|
fct_subscription_daily | One subscription on one calendar date | MRR, active subscriptions, churn |
fct_invoice_lines | One billed invoice line | Bookings, invoiced revenue, discounts |
fct_product_events | One tracked product event | Activation and feature adoption |
dim_accounts | One customer account | Segment and account attributes |
Build metrics on facts whose grain matches the question. MRR needs a subscription-date grain or an equivalent recurring revenue snapshot. Summing invoice lines may answer a bookings question, but it can invalidate an MRR revenue calculation.
Define entities and dimensions deliberately
In a semantic model, entities are the identifiers that support joins and traversal through the semantic graph. A primary entity might be subscription_id; a foreign entity might be account_id.
dbt’s entity guidance treats these as join keys, so name them consistently across related models. Avoid joining on a display name, email address, or mutable CRM label. In YAML, entities make those join paths explicit.
Dimensions are fields users group or filter by. They can include plan tier, region, acquisition channel, account segment, and time. The dimension documentation explains how dimensions attach to a semantic model’s primary entity.
Validate primary keys, relationships, and grain as part of your data quality checks before deployment.
A current-style YAML example
The following is illustrative YAML configuration for dbt versions using the latest metrics specification. Confirm property names against your installed release before deployment, because semantic layer YAML has changed across versions.
semantic_models:
  - name: subscription_daily
    model: ref('fct_subscription_daily')
    defaults:
      agg_time_dimension: snapshot_date


    entities:
      - name: subscription
        type: primary
        expr: subscription_id


      - name: account
        type: foreign
        expr: account_id


    dimensions:
      - name: snapshot_date
        type: time
        expr: snapshot_date
        type_params:
          time_granularity: day


      - name: plan_tier
        type: categorical
        expr: plan_tier


    metrics:
      - name: mrr
        type: simple
        type_params:
          expr: mrr_usd
          agg: sum
model points to the dbt relation that supplies the semantic model. agg_time_dimension sets the default field for time-based requests. The primary entity establishes the model’s row identity, while the foreign entity creates a controlled path to account attributes.
The mrr metric sums mrr_usd. In the newest specification, simple metrics replace legacy measures. Don’t relabel current simple metrics as legacy measures. Read dbt’s current semantic model reference before adapting older examples that use measures:.
Use the Right Metric Type
Current dbt documentation recognizes five metric types: simple, cumulative, derived, ratio, and conversion. The commonly repeated four-type list leaves out conversion metrics. In the semantic layer, these metric definitions tell MetricFlow how to evaluate each business metric, including query-time computation based on its declared type, time field, and relationships.
Simple and cumulative metrics
A simple metric applies an aggregation to a column. Examples include total MRR, count of active subscriptions, and total paid invoices. In the current dbt specification, simple metrics replace the legacy measures terminology, but the terms aren’t interchangeable across versions.
A cumulative metric aggregates a simple metric over time. It suits rolling 28-day active users, trailing 12-month revenue, and year-to-date bookings. Use it only when the default time dimension matches the business rule.
For example, a rolling active-user metric should use the product event date, not an account-created date. A time field that looks reasonable can still produce a misleading trend.
Ratio, derived, and conversion metrics
A ratio metric divides one metric by another. Trial conversion might divide converted trials by eligible trials. Define the denominator carefully, including whether canceled trials count.
A derived metric combines existing metrics through an expression. Gross retention can build on opening MRR, churned MRR, and contraction MRR, provided each component uses compatible grain and date logic.
A conversion metric measures a base event followed by a conversion event for the same entity inside a stated time window. It can model signup-to-activation or demo-request-to-opportunity conversion. Set the entity and window in plain business language before configuring it.
Build, Test, and Deploy the Layer Safely
Treat the semantic layer’s definitions like production code. A two-line metric change can alter a leadership dashboard, an incentive plan, or a board metric.
Start with a focused pilot
Pick one reporting slice for a one to two-week pilot. A practical choice is subscription health: MRR, active subscriptions, churned subscriptions, plan tier, and account segment.
Set acceptance criteria before building:
- Reconcile a completed month against finance-approved totals as a data quality check.
- Confirm that account and subscription joins don’t duplicate revenue.
- Test the metric in the BI workflow your team uses most.
- Record data warehouse runtime and scanned data for cold and repeated queries.
A pilot should prove that the model is accurate, usable, and affordable. Reconciliation and documented ownership also build data trust. It should not attempt to migrate every dashboard.
Add tests, ownership, and release controls
Use not_null and unique tests for primary keys in the relevant data models. Add relationship tests for foreign keys such as account_id. Then write singular tests for business rules that generic tests can’t catch, such as recognized revenue exceeding billed revenue. These checks make data quality measurable before release.
Assign an owner for each set of metric definitions. The owner doesn’t need to build every change, but they approve definition changes and document intent. Analytics engineers typically implement tests, models, and pull-request changes, while business owners approve meaning and use cases. Require pull request review when edits affect shared entities, dimensions, or revenue logic. Together, these controls provide practical data governance.
For dbt Cloud administration of the dbt semantic layer, teams select a deployment environment, configure credentials, and grant read access to relevant schemas. Governed read access supports self-service analytics without granting unrestricted access to raw data. The dbt Semantic Layer FAQ is a useful starting point for separating project configuration from platform setup.
Control Query-Time Cost and Performance
Central definitions improve consistency, but they don’t remove data warehouse constraints.
Why flexible requests can cost more
A semantic layer request may resolve joins, filters, time spines, and aggregations dynamically. That query-time computation can cost more with complex requests.
Costs rise when users combine high-cardinality dimensions, request large date ranges, or repeatedly scan event-level facts. Review query logs during the pilot to identify expensive query-time computation. Look for repeated full-table scans, slow joins, and dashboard traffic competing with transformation jobs.
Also separate ELT and BI workloads where your warehouse supports it, because scheduled dbt runs can collide with morning reporting. Set sensible defaults in BI tools, limit open-ended date ranges, expose approved dimensions first, and avoid making every raw event property available for self-service grouping.
When pre-aggregation fits better
For recurring dashboards with predictable slices, materialized models may be simpler than on-demand semantic queries. A daily account-product summary is one useful pre-aggregation, making activation reporting faster and easier to audit.
Cube takes a different approach. Its documentation describes background summaries that refresh alongside query caching. That can suit embedded analytics or repeated, latency-sensitive workloads. It also introduces another modeling and operational system to maintain.
Use a dbt metrics layer when definition reuse and lineage matter most, especially when query-time computation is acceptable. Use materialized results when workload patterns are stable. Choose pre-aggregation when repeated interactive queries need predictable response times.
FAQs About Building a dbt Metrics Layer
Does a semantic layer replace dbt models?
No. A dbt semantic layer depends on clean dbt models. Build staging models for source cleanup, intermediate models for reusable logic, and marts or facts with a clear grain. The layer then exposes approved definitions on top of those relations.
Why don’t centralized definitions automatically create data trust?
Teams still need agreement on metric definitions. “Active customer” may mean a paid account, an account with a login, or an account using a key feature. Document the business rule, name the owner, test the model, and publish the definition alongside the metric. A semantic layer improves consistency only when teams agree on these standards.
Should a small SaaS team adopt this immediately?
Start when multiple dashboards or teams need the same business metrics, including shared revenue, customer, or funnel metrics. A solo founder with one dashboard may get more value from tested dbt marts first. As logic starts repeating, governed definitions can support self-service analytics and prevent reporting drift. A small pilot can provide that value without overbuilding.
Build Consistency Before Complexity
A strong semantic layer starts with a few trusted SaaS facts, clear row grain, and shared definitions that remain a single source of truth when your BI tool changes.
Start with the revenue, retention, or growth business metrics definition that causes the most disagreement. When its lineage, tests, owner, and warehouse cost are visible, metric consistency becomes an operating habit instead of a dashboard aspiration.
